
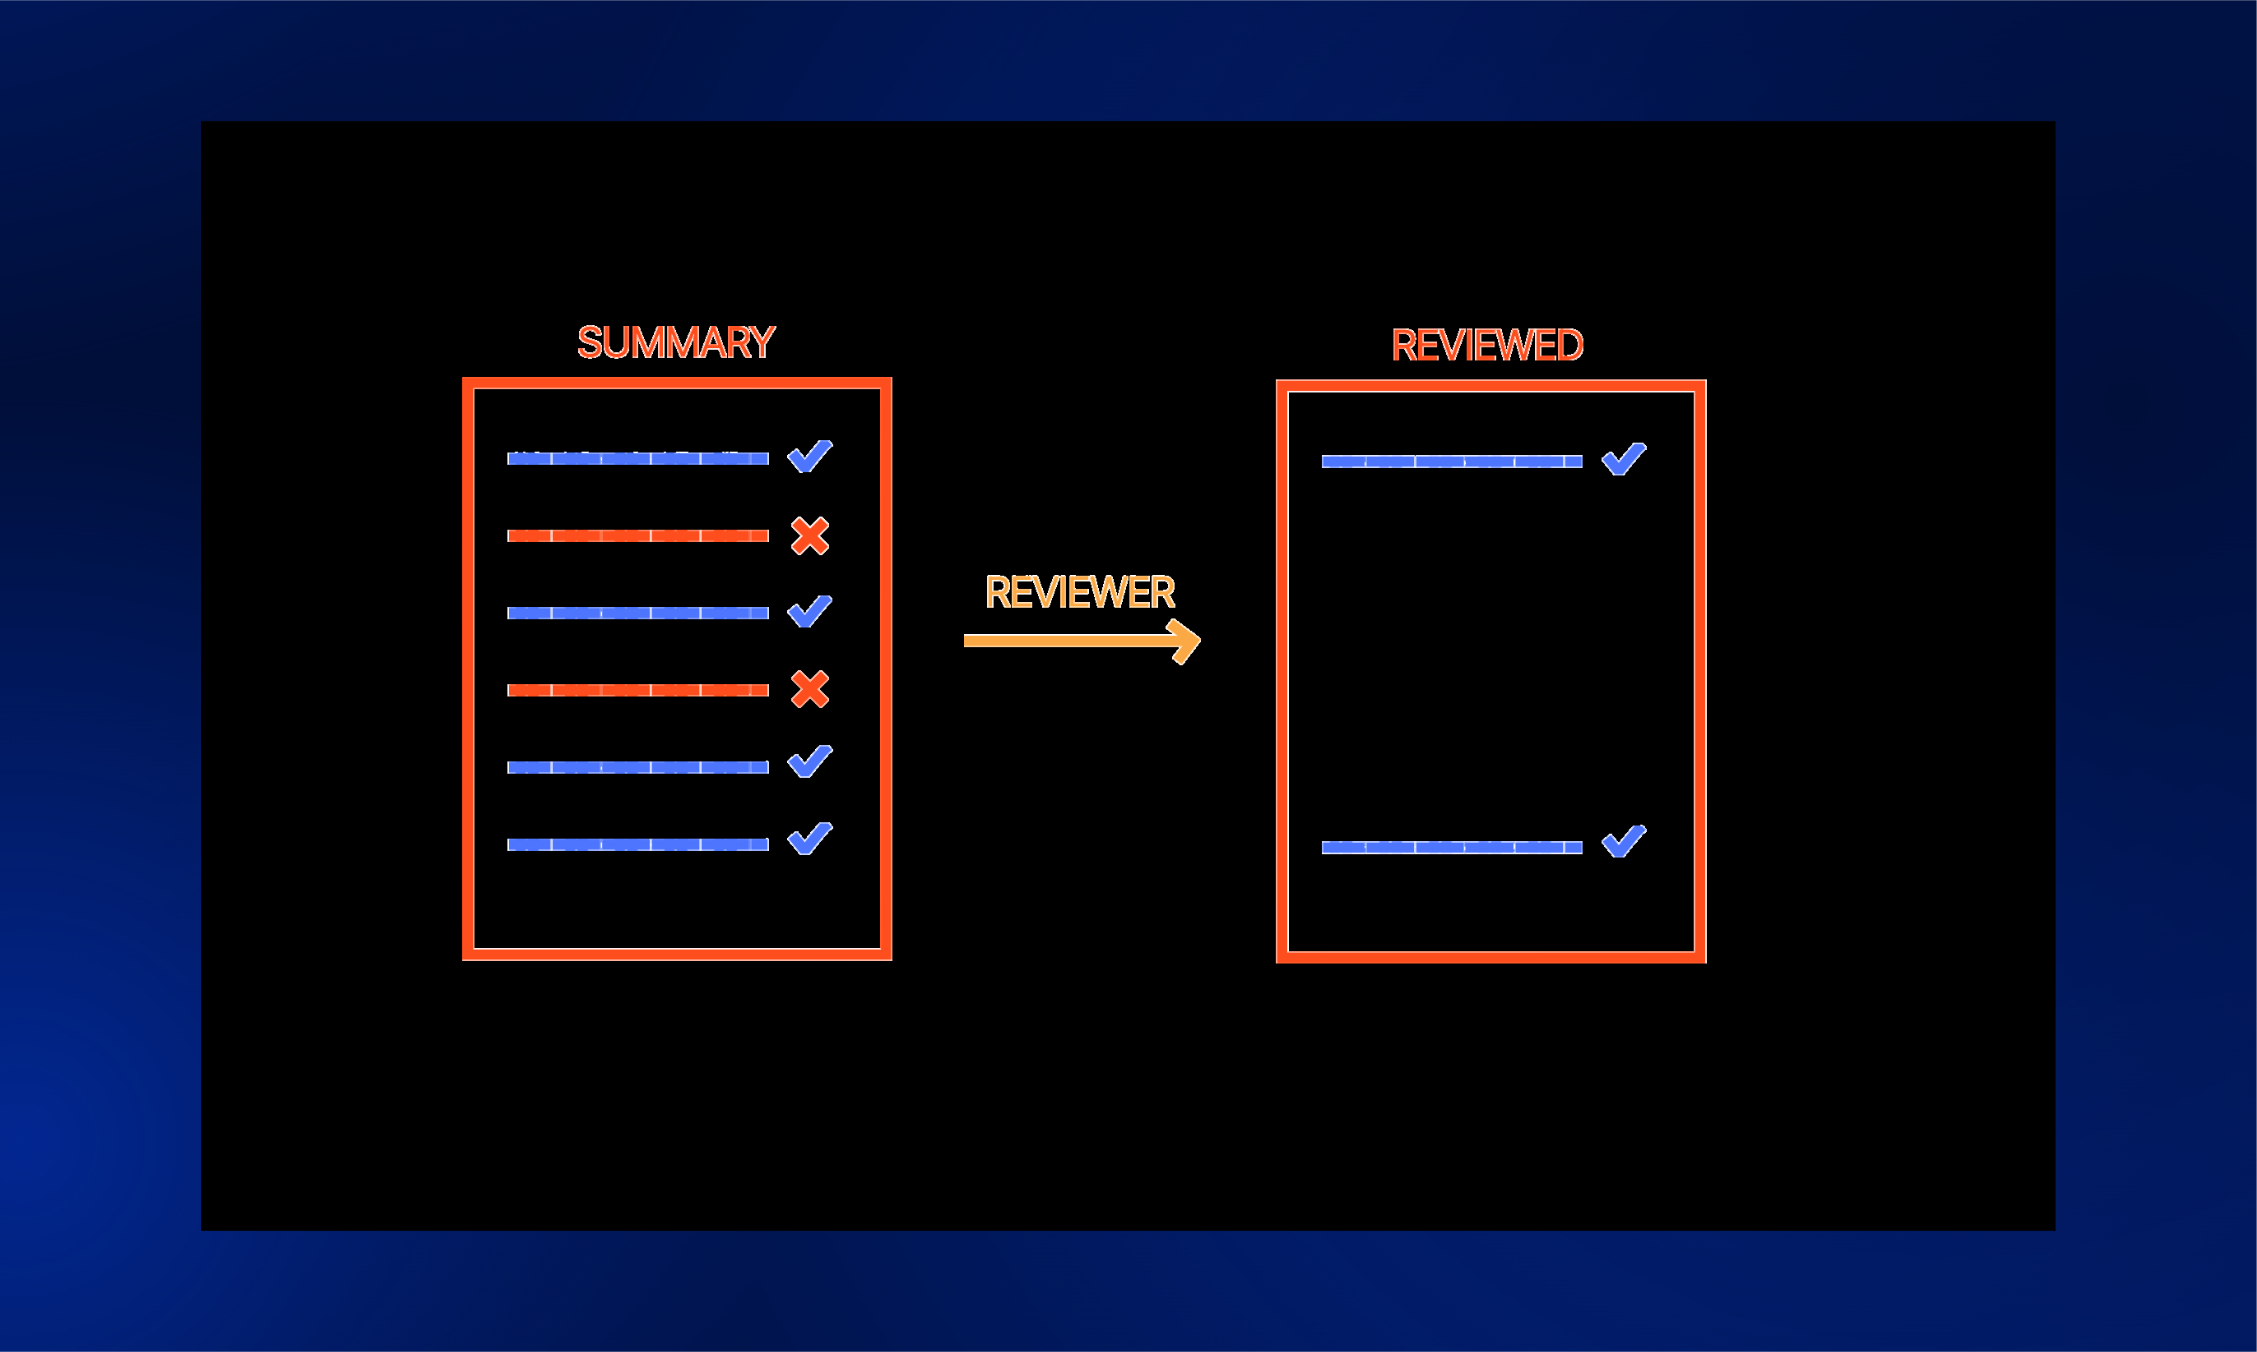

Have you ever asked one model to summarize something, then used another model to check whether the summary was trustworthy?
I have. I used a local model to summarize meeting transcripts I couldn’t attend. When I read the summaries, I noticed claims that were not in the meetings at all.
I didn’t want to check every claim myself, so I asked a second model to review the summaries for me.
I expected the reviewer model to do well. After all, checking a summary should be easier than writing one.
This article walks through what I found.
TL;DR
Here is the short version:
- A reviewer is not automatically a safety layer.
qwen3:8bcaught 3 of 12,qwen2.5:14bcaught 6 of 12, andllama3.1:8bcaught 9 of 12. - More catches did not always mean a better reviewer.
qwen3:30b-a3bcaught more unsupported claims thanqwen2.5:14b(10 of 12 vs. 6 of 12), but it also removed more supported claims (10 of 23 vs. 2 of 23). - A model trained for support judgment worked best.
bespoke-minicheck:7bmatched the strongest general reviewers on unsupported claims, removed no true claims, while running faster.
What Is a Reviewer Model?
A reviewer model is a second model call that checks the first model’s output against the source.
The reviewer might remove unsupported claims, rewrite the summary, flag suspicious claims, or return a structured list of problems.
For meeting summaries, the setup is simple: one model summarizes the transcript, and a second model reviews that summary against the transcript.
Here is the code example of what it looks like:
draft = summarizer_model(f"Summarize this transcript:\n{transcript}")
final = reviewer_model(
    "Review this summary against the transcript. Remove anything unsupported.\n"
    f"Transcript:\n{transcript}\n\nSummary:\n{draft}"
)
Here is the kind of unsupported claim the reviewer should catch.
The transcript says the funding risk comes from Proposition Six passing:
TRANSCRIPT
"If SB six does pass, how much we would stand to lose"

  Prop Six PASSES ─────▶ city loses funding
The summary changes the condition. It says the funding risk comes from opposing Proposition Six:
DRAFT SUMMARY
"Opposing Proposition Six could result in the loss"

  OPPOSING Prop Six ───▶ city loses funding
  ▲▲▲▲▲▲▲▲
  only this end changed
The reviewer should remove the unsupported condition: “Opposing Proposition Six could result in the loss.”
The rest of the article tests how well the reviewer models handled that task.
What Makes a Reviewer Good?
To evaluate the reviewer models, I measured two things:
- Recall: How many unsupported claims did the reviewer catch?
- Precision: How many removed claims were actually unsupported?
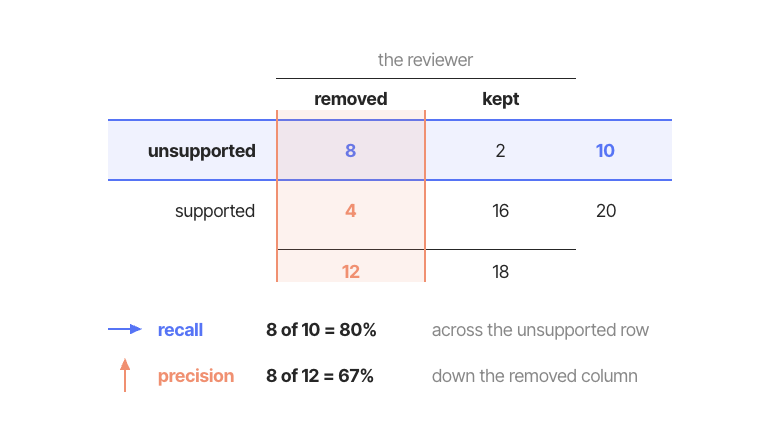
I care about both because they catch different failures:
- A reviewer can get high recall by removing anything suspicious, including supported claims.
- A reviewer can get high precision by removing only safe, obvious errors, while missing subtler unsupported claims.
A production reviewer should catch most unsupported claims without removing supported ones. For this experiment, that meant roughly 80% recall with 0 supported claims removed.
Setup
To make the experiment reproducible, I used a public dataset: 9 council meeting transcripts from MeetingBank.
The summaries came from qwen3:8b. Each one contained at least one claim the transcript did not support.
I read the transcripts and labeled each claim as supported or unsupported. In total, there were 35 claims:
- 23 supported claims
- 12 unsupported claims
I tested five general-purpose reviewer models to cover a variety of options:
| Reviewer | What it is | What it returns |
|---|---|---|
qwen3:8b |
The same model that wrote the summary | A corrected summary |
llama3.1:8b |
A different model of similar size | A corrected summary |
qwen2.5:14b |
A somewhat larger general model | A corrected summary |
qwen3.8:27b-mlx |
A newer high-capacity reviewer | A corrected summary |
qwen3:30b-a3b |
A newer high-capacity reviewer with fewer active parameters | A corrected summary |
All models ran through Ollama with temperature=0, seed=0, and num_ctx=16384, on a MacBook Pro M5 Pro with 64 GB of memory.
How I Scored the Reviewers
For each claim from the first summary, I needed both the ground truth and the reviewer action:
- Ground truth: whether the transcript supported the claim.
- Reviewer action: whether the claim stayed in the reviewed summary or disappeared.
| Human label | After review | Meaning |
|---|---|---|
| Unsupported | Disappeared | The reviewer caught a problem |
| Unsupported | Survived | The reviewer missed a problem |
| Supported | Disappeared | The reviewer removed true content |
| Supported | Survived | The reviewer kept true content |
Results
Which General Reviewer Was Best?
At first, the pattern looks simple: larger reviewers caught more unsupported claims.
qwen3:8b         caught  3 of 12 unsupported claims
qwen2.5:14b      caught  6 of 12 unsupported claims
llama3.1:8b      caught  9 of 12 unsupported claims
qwen3.8:27b-mlx  caught 10 of 12 unsupported claims
qwen3:30b-a3b    caught 10 of 12 unsupported claims
But catching more bad claims is only part of it. A reviewer can look better by removing more claims overall, including claims the transcript actually supports.
qwen3:8b         wrongly removed  2 of 23 supported claims
qwen2.5:14b      wrongly removed  2 of 23 supported claims
llama3.1:8b      wrongly removed  7 of 23 supported claims
qwen3.8:27b-mlx  wrongly removed  1 of 23 supported claims
qwen3:30b-a3b    wrongly removed 10 of 23 supported claims
Looked at this way, the pattern looks weaker. One of the larger reviewers, qwen3:30b-a3b, caught more unsupported claims than the smaller ones, but it also removed more supported ones.
To compare them fairly, I needed both numbers side by side: what they caught and what they wrongly removed.
| Reviewer | Unsupported claims caught | Supported claims wrongly removed | Recall | Precision |
|---|---|---|---|---|
qwen3:8b |
3 of 12 | 2 of 23 | 25% | 60% |
qwen2.5:14b |
6 of 12 | 2 of 23 | 50% | 75% |
llama3.1:8b |
9 of 12 | 7 of 23 | 75% | 56% |
qwen3:30b-a3b |
10 of 12 | 10 of 23 | 83% | 50% |
qwen3.8:27b-mlx |
10 of 12 | 1 of 23 | 83% | 91% |
That makes qwen3.8:27b-mlx the best general reviewer in this test. It caught 10 of 12 unsupported claims while removing only 1 supported claim.
qwen3:30b-a3b caught the same 10 unsupported claims, but it also removed 10 supported claims.
Did the Reviewers Catch the Same Claims?
Do different reviewer models catch the same unsupported claims? Not really. The grid below shows which reviewer removed which claim.
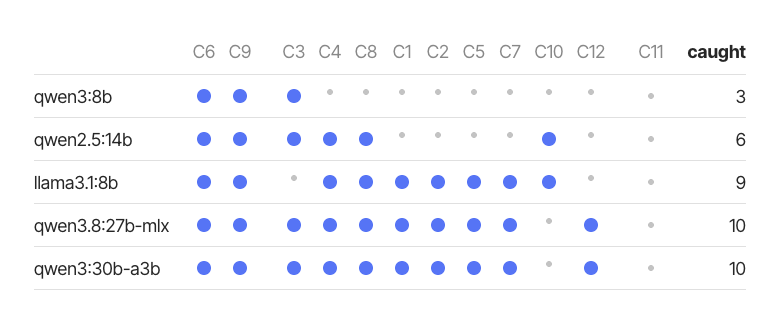
Only 2 of the 12 unsupported claims were caught by every reviewer. One claim was missed by every reviewer.
That means the reviewer choice still mattered. Most unsupported claims were caught by some models and missed by others, so the final summary depended on which model did the review.
How to Make Review More Reliable
These results made one thing clear: I would not let a general reviewer silently delete claims on its own. Some unsupported claims survived, and some supported claims disappeared.
To make the review step safer, I tried three changes:
- Use a model trained for support judgment
- Flag claims instead of deleting them
- Remove a claim only when multiple reviewers flag it
Try a Model Trained for Support Judgment
The general reviewers were being asked to rewrite a summary, but the real task was narrower: decide whether each claim was supported. Since there is a model trained for that exact judgment, I wanted to test whether it would do better.
The model I chose was bespoke-minicheck:7b, an Ollama model for grounded fact-checking. It takes a source document and a claim, then predicts whether the source supports the claim.
Compared with the general reviewers, bespoke-minicheck:7b changed both the input and the output:
- Input: It saw one claim at a time, not the full summary.
- Output: It returned a support label, not a rewritten summary.
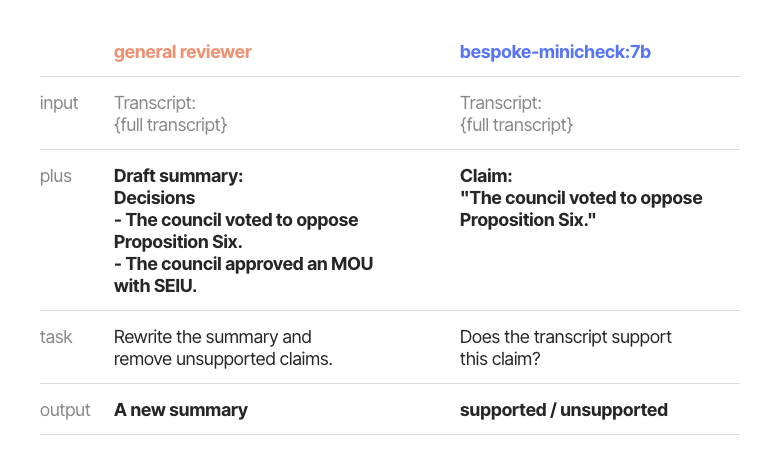
Let’s compare bespoke-minicheck:7b with other general reviewers.
| Reviewer | Unsupported claims caught | Supported claims wrongly removed | Total time |
|---|---|---|---|
qwen3:8b |
3 of 12 | 2 of 23 | 27.7s |
qwen2.5:14b |
6 of 12 | 2 of 23 | 50.5s |
llama3.1:8b |
9 of 12 | 7 of 23 | 40.3s |
qwen3:30b-a3b |
10 of 12 | 10 of 23 | 129.9s |
qwen3.8:27b-mlx |
10 of 12 | 1 of 23 | 63.0s |
bespoke-minicheck:7b |
10 of 12 | 0 of 23 | 10.2s |
Compared with the two high-capacity reviewers, bespoke-minicheck:7b had the strongest overall result:
- It caught the same 10 unsupported claims.
- It removed no supported claims.
- It finished faster than every rewrite-based reviewer.
Flag Instead of Delete
One way to avoid bad deletions is to stop deleting. Instead, the reviewer can flag claims for a human to inspect.
That keeps true content recoverable. If the reviewer flags a supported claim by mistake, the human can keep it.
The downside is that unflagged claims may not get checked. The table below assumes the human reads every flagged claim and ignores every unflagged claim:
| Flagger | Human reads | Slips through unread |
|---|---|---|
qwen3:8b self-review |
5 of 35, 14% | 9 of 12, 75% |
qwen2.5:14b |
8 of 35, 23% | 6 of 12, 50% |
llama3.1:8b |
16 of 35, 46% | 3 of 12, 25% |
The numbers show both sides of flagging:
- The human does less work: 5 to 16 claims reviewed instead of 35.
- The human can recover false flags instead of losing true content automatically.
- But unread does not mean safe. With a cautious flagger like
qwen3:8b, 75% of unsupported claims were missed.
Require Agreement Only When Misses Are Acceptable
You could also try a voting rule: run several reviewers, then delete only when one, two, or all three reviewers flag the same claim.
I tested three rules:
| Rule | Caught | Wrongly removed | Precision |
|---|---|---|---|
| Any 1 of 3 flags it | 10 of 12 | 7 of 23 | 59% |
| 2 of 3 agree | 6 of 12 | 4 of 23 | 60% |
| All 3 agree | 2 of 12 | 0 of 23 | 100% |
Each rule fails in a different way:
- Any 1 of 3 catches more unsupported claims, but wrongly removes 7 supported claims.
- 2 of 3 agree still removes 4 supported claims and misses half the unsupported ones.
- All 3 agree removes no supported claims, but catches only 2 of 12 unsupported claims.
If missed unsupported claims are acceptable in your workflow, reviewer agreement can reduce bad removals. Otherwise, I would not rely on it as the main safety layer.
How to Judge a Reviewer
The main lesson is not about which model is best for reviewing. It is about how to judge reviewer models.
A reviewer can improve an output, but it can also make new mistakes while making the answer look cleaner. If you only count what it catches, you miss what it changed, removed, or added by mistake.
When you test a reviewer, measure the full effect:
- Did it catch the errors you care about?
- Did it damage correct parts of the output?
- Did it reduce human work, or just move the work elsewhere?
If the biggest risk is showing users false information, optimize for catching more errors.
If the biggest risk is losing important information, optimize for removing fewer supported claims.
My advice: make the reviewer prove itself. Test it on a small labeled set, and check both sides: what it improves and what it gets wrong before trusting it.
Running the Code Yourself
The companion files are available on GitHub. The folder includes the transcripts, labeled claims, reviewer outputs, and the JSON file behind every number above.
Pull the models:
ollama pull qwen3:8b && ollama pull llama3.1:8b && ollama pull qwen2.5:14b
ollama pull qwen3.8:27b-mlx && ollama pull qwen3:30b-a3b
ollama pull bespoke-minicheck:7b
Run the pipeline from the companion folder:
cd notebooks/model-reviewing-model-reliability

uv run scripts/natural.py .
uv run scripts/crossmodel.py
uv run scripts/agree.py
uv run scripts/timing.py
References
- Self-Refine: Iterative Refinement with Self-Feedback (Madaan et al., 2023): Shows that iterative self-feedback can improve model outputs across several tasks, the positive result behind many review-and-revise workflows.
- Large Language Models Cannot Self-Correct Reasoning Yet (Huang et al., 2024): Reports that self-correction can fail or degrade performance in reasoning tasks, motivating direct measurement instead of assuming review helps.
- MiniCheck: Efficient Fact-Checking of LLMs on Grounding Documents (Tang et al., 2024): Introduces small models for checking whether generated claims are grounded in source documents.
- LLM Summarizers Skip the Identification Step (William Gieng, 2026): The clipping that motivated this experiment’s question about whether a reviewer stage actually removes unsupported summary claims.


